Paris startup Physicl has raised $10 million in seed funding to build one of robotics’ least glamorous bottlenecks: training data. TechCrunch reports the round was led by Inovia Capital with U.S. Venture Partners participating, announced 6 November alongside the launch of Studio, Physicl’s tool for generating synthetic training scenes where a robot’s model is about to fail. The pitch in one line: robots need practice in strange situations, and someone finally has a factory for them.
🔍 THE BOTTOM LINE
Robotics keeps learning the hard way that physical-world data is the scarce resource, not compute. Physicl’s answer is to rebuild the world in 3D and generate the failures on demand — and its early proof point, a world-model maker cutting error rates by more than half, is exactly the kind of number the synthetic-training-data bet needs to survive contact with real deployments.
Why robot people are frustrated with video
The backdrop, as Dealroom’s coverage puts it, is that researchers building physical AI have been frustrated by the poor returns of training robots on video and the expense of gathering data through remote operation. Simulated worlds look like the fix, but keeping them faithful to real-world physics has proven difficult. Models trained on footage of a tidy kitchen are thrown by a cup half hidden behind a bag, a shadow crossing the counter, a box stacked slightly out of place — situations that are hard to capture in bulk and, once recorded, impossible to replay with the lighting changed.
Founder and CEO Alex de Vigan arrives at this problem by accident of history. He spent a decade building nfinite, a Paris company that made 3D product imagery for online retailers and raised $100 million in 2022 before generative AI started eating its market. “What we created 10 years ago, without knowing it, was basically an agentic workflow to transform unstructured information into high fidelity 3D,” de Vigan told TechCrunch. Robotics and world-model teams started asking for precisely labelled versions of the situations their models failed on, in volumes of thousands — and the pivot was born.
Studio: a targeted failure generator
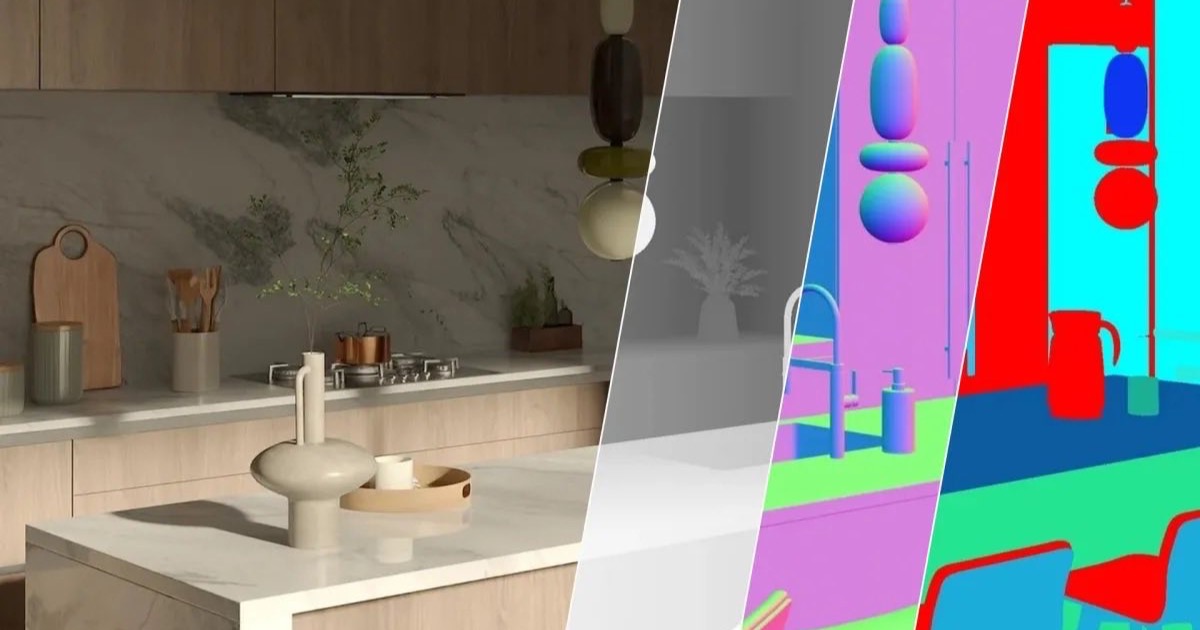
Studio, Physicl’s first product, ships with 10,000 ground-truth 3D environments and more than 100,000 assets that can combine into billions of scene variations, per the company’s release. The workflow: a researcher describes in plain language the situation their model fails on, Studio proposes matching scenes and variations, the researcher adjusts ranges — lighting, time of day, clutter, camera height and path can each change independently — and the system renders the result while recording the conditions behind every frame.
The ground-truth part is the interesting engineering claim. Depth maps, surface normals, segmentation and bounding boxes come from the same 3D scene that produces the image, rather than being predicted from the render — labelling by construction, not annotation. De Vigan imagines customers feeding trillions of images or millions of hours of lidar capture into the platform and generating billions of permutations from them. Studio is in beta and free during that period, with access opening in waves.
The early proof point, with a world-model customer
The credibility of the whole pitch currently rests on one collaboration. SpAItial, a world-model company whose Echo-3 shipped last week, trained with Physicl data and more than halved the reconstruction error of its room-building model, an evaluation from founder Matthias Niessner’s team at TUM. Niessner’s vision of where this goes is instructive: “You’re running Claude, and it checks, ‘Oh, I need more data of this in my training,’ and then it auto generates that data, depending on the training state.”
That is the long game — training data generated reactively by the model itself, closing its own gaps. It is also a long way from a beta tool and a single published evaluation. Dealroom notes the round ranks in the top 3% of all-time French enterprise-software seeds, which tells you investors think the data-and-simulation layer of physical AI is real infrastructure. Whether it is durable infrastructure depends on evidence that synthetic pre-training survives contact with real hardware — and, as de Vigan himself admits, “the space is very young and very blurry sometimes.”
The shovels-for-the-gold-rush pattern continues
It was already a theme this week. Yesterday Serve Robotics opened its fleet data and connectivity to other robot builders as the AWS-for-robots play, Nvidia put out the first open humanoid foundation model, and Physicl now sells the training substrate under all of it. The pattern echoes our earlier reckoning with who actually funds the robot floor: when a hardware race gets expensive and uncertain, the steadier money moves to the picks and shovels — chips, data, simulation, connectivity.
For a country with New Zealand’s robotics footprint, the simulation-data economy is the accessible end of the field. You don’t need a fleet or a factory to train or evaluate models here; the compute and the 3D environments are rentable. What you need is the modelling talent — which is exactly what Physicl’s own story suggests: this company was built by e-commerce rendering people, not robot operators. The barriers to entry in physical AI’s data layer are domain skills and pipeline engineering, not warehouses.
Roughly 30 people run Physicl across New York, San Francisco and Paris; most spent six years building 3D production systems with de Vigan, per Unite.AI. The funding will go on the team and the platform as robotics and world models move toward deployment.
❓ FAQ
What does Physicl actually sell? Synthetic training data and the tooling to generate it. Studio holds 10,000 ground-truth 3D environments and 100,000 assets; researchers describe a model’s weak spot and generate targeted scenes — a cup in shadow, a cluttered counter — with perfect labels derived from the 3D scene itself.
Who is behind the round? $10 million led by Inovia Capital with U.S. Venture Partners participating, per TechCrunch. The company’s release also lists Insight Partners among its backers.
Is synthetic training data proven to work for robots? Partially. The strongest public result is SpAItial cutting its room-reconstruction error by more than half after training on Physicl data — a company evaluation, not an independent benchmark. The industry consensus is still forming, and de Vigan acknowledges the space is young.
Why does this matter for world models? World models — systems like SpAItial’s that predict how scenes evolve — need physically plausible training scenes at scale. Real capture can’t replay a scene with changed lighting or object positions; synthetic generation can, which is the core of Physicl’s pitch.
🔍 THE BOTTOM LINE
The money behind this round is really a thesis: in physical AI, data scarcity — not model architecture and not compute — is the binding constraint, and the companies that own the generation pipeline will sit somewhere close to the top of the stack. Physicl’s early numbers give the thesis its first real evidence; the next year of robot deployments will tell us whether synthetic edge cases transfer to factory floors or stay pretty in the simulator.
📰 Sources
- TechCrunch — funding and Studio details, de Vigan interview
- The Next Web — round details, SpAItial/TUM evaluation
- GlobeNewswire — Physicl press release
- Unite.AI
- Dealroom